Home / Demos / Triton softmax kernel on a GPU slice
GPU Triton 3.6 · PyTorch 2.10 · RTX 5090 slice
Triton softmax kernel on a GPU slice
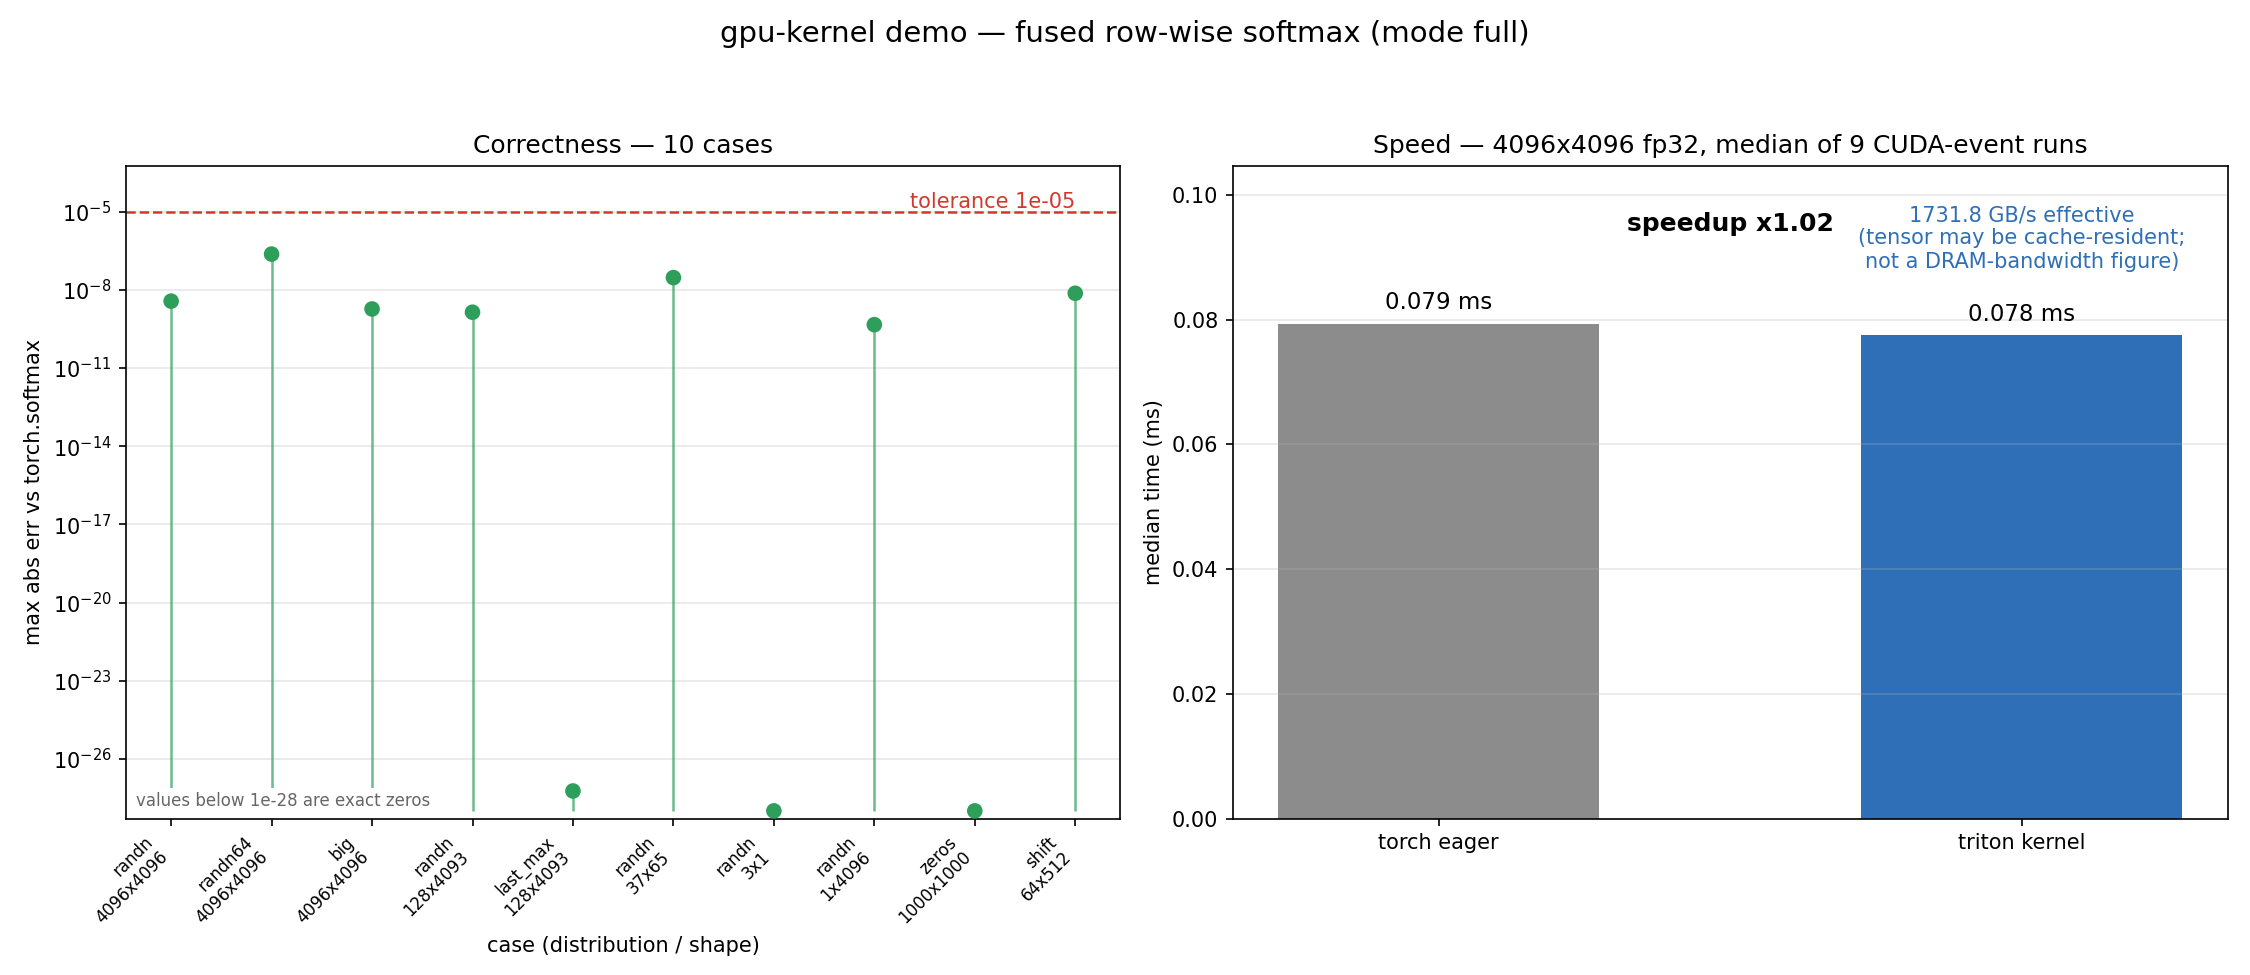
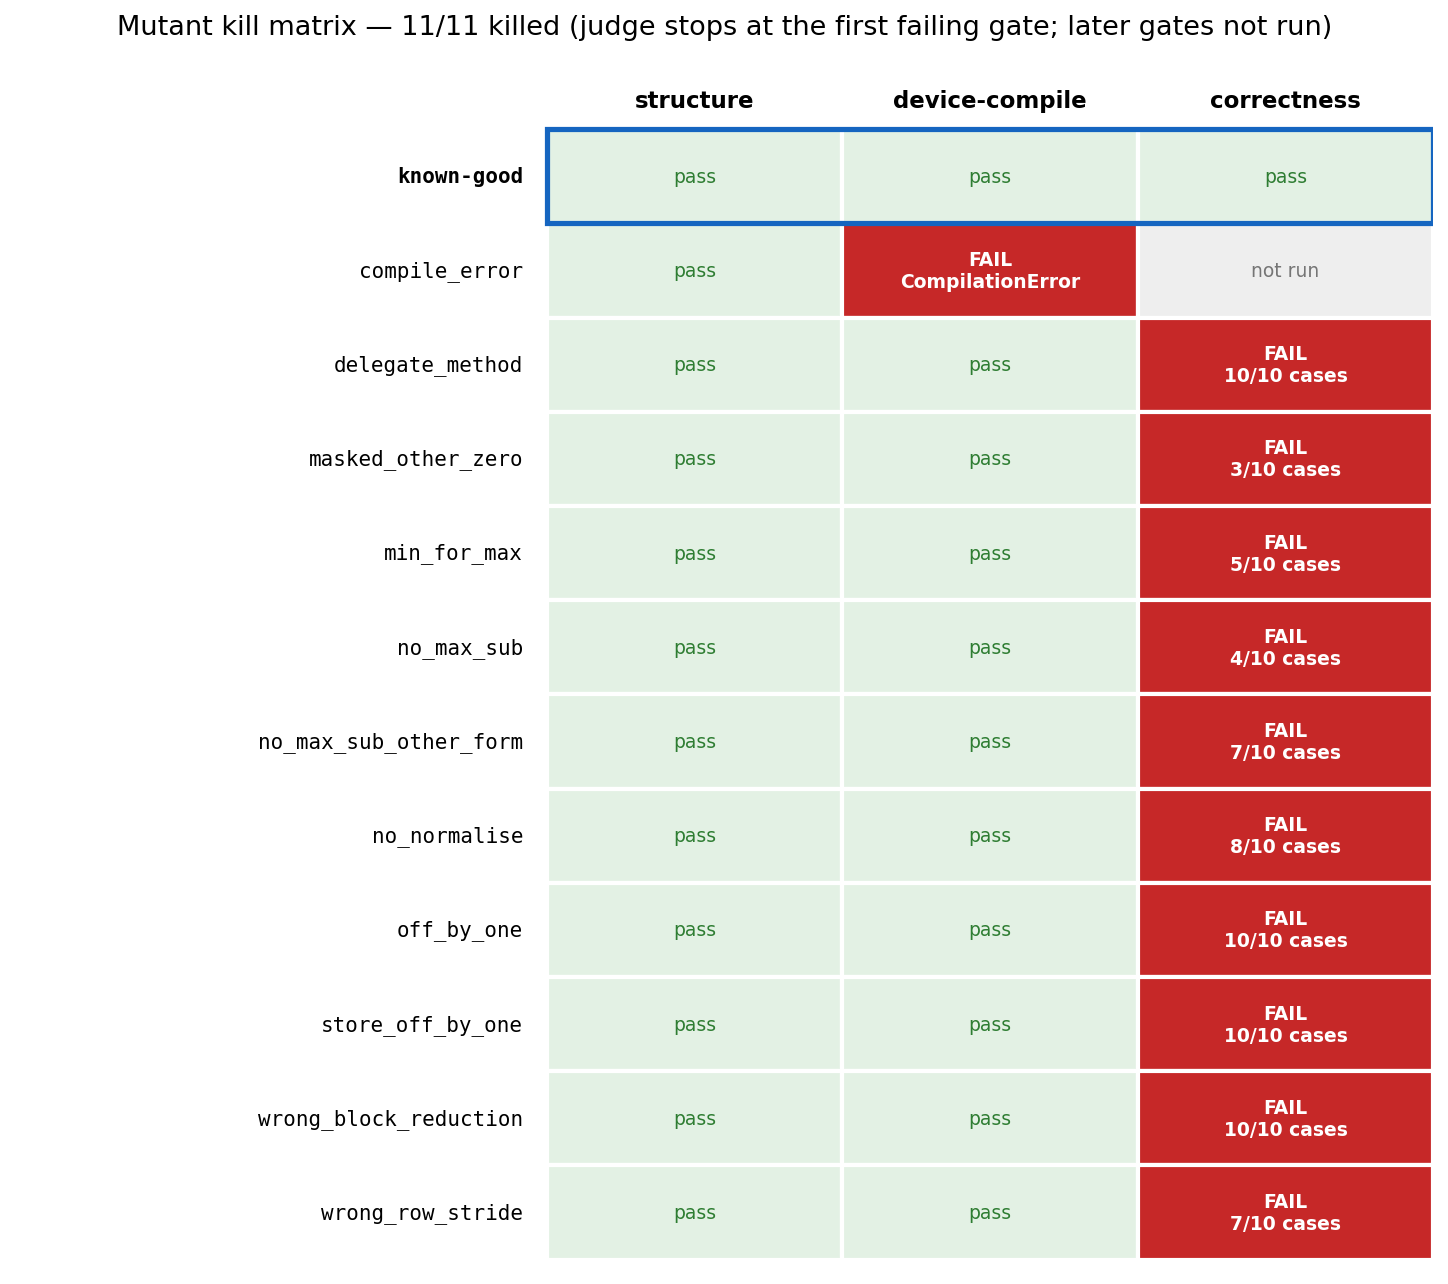
The agent writes a fused row-wise softmax as a single Triton kernel. The judge compiles it to real device code (sm_80 and sm_90), compares it with torch eager over odd shapes and adversarial inputs, checks that rows sum to 1, shift invariance and an untouched input, and only then reports speed honestly: the median of CUDA-event timings against torch.softmax. It runs on a 1 GiB VRAM slice of an RTX 5090, or in a CPU-only check mode.
Measured
all
≤ 1e-5
reported, not gated
self-test, ≥ 90 % required
reproduced Independently reproduced on the CPU path; GPU numbers are from one run on a 1 GiB RTX 5090 slice. Numbers from the demo's README and receipt.
Ask your agent
With the sandbox plugin or any agent that can use a sandbox, paste:
Create a fresh sandbox (GPU lease, `vram_gb: 1` if GPU access is on my key; otherwise a plain sandbox and the judge's `--cpu-check` mode). Inside it, clone https://github.com/agent-next/sandbox at ref `main`, then read `cookbook/gpu-kernel/SPEC.md` carefully: implement the fused row-wise softmax as a single Triton kernel in one file, `kernel.py`, exposing `softmax(x)`, `KERNEL`, `SIGNATURE` and `CONSTEXPRS` exactly as the spec's artifact contract says. Do not delegate to torch's own softmax. Run `cookbook/gpu-kernel/judge/setup.sh`, write your kernel, then iterate with `bash cookbook/gpu-kernel/judge/grade.sh /path/to/your/kernel.py --json /tmp/v.json` until every gate passes. Report the verdict JSON, then kill the sandbox and confirm it is gone.Or run it yourself
Creates a sandbox, installs the pinned tools, runs the judge's self-test, grades the known-good example, prints the verdict and kills the sandbox.
pip install "git+https://github.com/agent-next/sandbox#subdirectory=cli"
export SBX_API_KEY=<your key>  # from the console
git clone --depth 1 https://github.com/agent-next/sandbox && cd sandbox
python3 cookbook/gpu-kernel/run.py          # CPU sandbox: --cpu-check judge
python3 cookbook/gpu-kernel/run.py --gpu    # 1 GiB GPU slice: full judge
No key? Run the judge on any Debian 12 box
# from cookbook/gpu-kernel/
bash judge/setup.sh
bash judge/selftest.sh
bash judge/grade.sh examples/good/kernel.py
Results
Why a sandbox
Kernel work is messy: the sandbox pins a torch/Triton toolchain, runs untrusted agent-written kernels away from your machine, and the GPU lease is destroyed and verified gone afterwards.
Measured wall time
| Step | Wall time |
|---|---|
judge/setup.sh (cold, CPU path) | ~1 min |
judge/selftest.sh (CPU path) | ~2 min |
judge/grade.sh (CPU path) | ~11 s |
Limits, plainly
- Correctness is the gate; speed is reported, not gated (--speed-target exists if you want it).
- The CPU check proves the kernel compiles to device code and is numerically right; GPU speed needs the GPU lease, which must be enabled on your key.
- The ~1x speedup is expected: torch's softmax is already bandwidth-bound on this shape.
Source
Demo folder · SPEC · RECEIPT · REPRODUCE — pinned at ba328e6
Run one yourself
Sign in with GitHub for a free key with 10 sandbox-hours. Every demo above finishes in minutes and kills its sandbox when it is done.